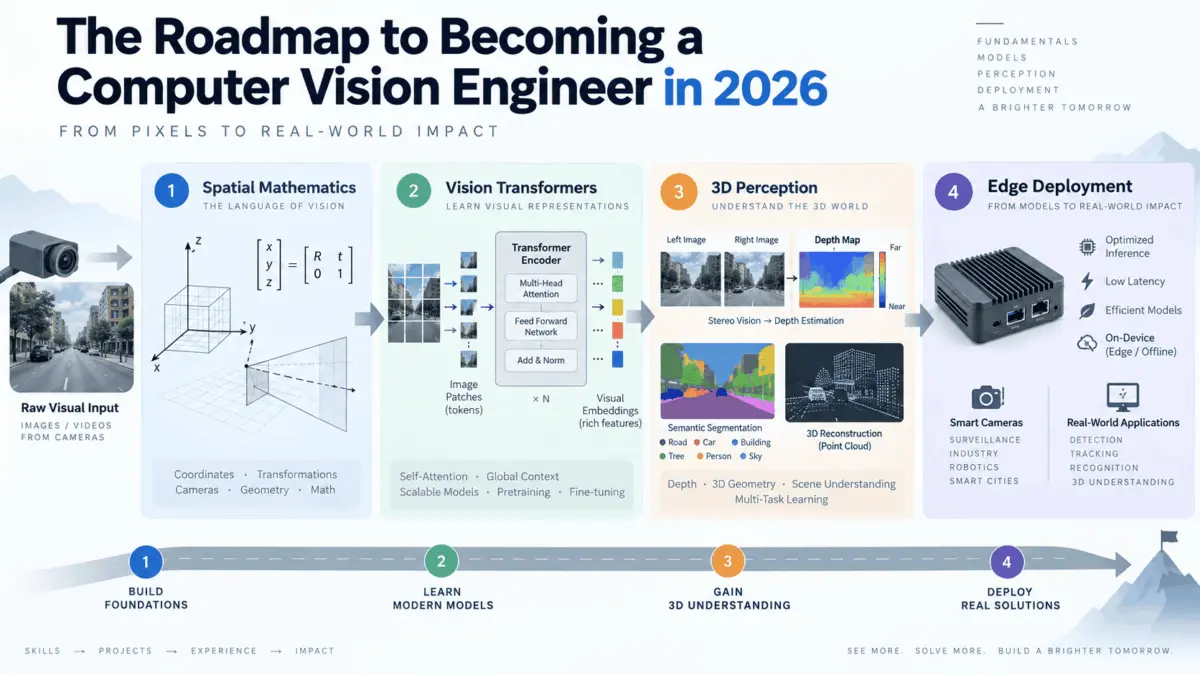
Computer vision has evolved profoundly, moving far beyond the traditional boundaries of basic object detection and image classification. By 2026, computer vision engineers are operating at the intricate intersection of foundation models, spatial computing, and embedded hardware. Today’s professionals are tasked with building systems that not only perceive the visual world in real time, but also reason over it and take meaningful action based on that visual data.
The modern industry demand for engineers who can operate across this complex, full stack is growing steadily across multiple sectors. Autonomous vehicles, robotic warehouses, advanced medical imaging platforms, and spatial computing devices all share a common, critical need: they require technical talent that understands far more than just model architecture. Modern engineers must master the entire pipeline, managing the journey smoothly from physical sensors all the way to production-level inference.
To address this growing industrial complexity, technical educators and industry leaders have mapped out a progressive path for professional development. This structured roadmap covers four distinct stages, progressing from spatial mathematics and foundational vision primitives up through edge deployment and hardware-aware optimization. Each stage builds directly upon the previous one, ensuring that practitioners develop a robust foundation before tackling advanced multi-modal systems.
The journey begins at the foundational level with spatial mathematics and fundamental vision primitives. Every modern computer vision system is ultimately a mechanism for reasoning about geometry. Before working with contemporary vision architectures, engineers need a working, practical understanding of the mathematics that make visual reasoning possible in physical environments.
The core concepts at this initial stage include matrix transformations, coordinate frames, projective geometry, and multi-view geometry. Far from being merely academic or abstract, these mathematical principles determine precisely how a physical camera maps a three-dimensional world onto a two-dimensional digital sensor, how two distinct camera views can mathematically reconstruct depth, and how coordinate systems relate to one another across sensors in a complex, multi-camera hardware rig.
On the practical implementation side, professionals must build deep fluency with PyTorch for tensor manipulation, which firmly remains the industry standard framework for both academic vision research and production environments. This technical capability must be paired with synthetic data augmentation pipelines to ensure models generalize well. Libraries like Albumentations have become ubiquitous, offering fast and composable transforms that simulate lighting variations, geometric distortions, and object occlusions without the costly burden of collecting entirely new physical datasets.
Feature representation forms the third major pillar of this foundational stage. Engineers must understand the distinct functional differences between traditional convolutional backbones like ResNet or EfficientNet and modern attention-based architectures. Furthermore, contrastive representation learning—where models learn effectively by comparing similar and dissimilar examples—has become a standard industry technique for learning useful embeddings before downstream task-specific fine-tuning takes place.
As practitioners advance to the second stage of the professional landscape, they encounter the massive shift from convolutional neural networks to transformer-based architectures. Vision Transformers process images as sequences of fixed-size patches, applying self-attention mechanisms across those patches rather than relying on local convolutional filters. Subsequent developments, such as Swin Transformers, have extended this capability by introducing hierarchical, windowed attention that makes transformer-based approaches practical for high-resolution visual inputs.
Beyond pure vision architectures, a more significant development in the field is the rapid emergence of vision-language models. Models like CLIP and SigLIP learn joint embeddings across both image and text modalities through large-scale contrastive training on web-scraped datasets. The practical result of this technological leap is true open-vocabulary understanding, allowing engineers and systems to query a visual scene using natural language descriptions rather than being restricted to rigid, predefined class labels.
This capability unlocks advanced techniques such as open-vocabulary detection. Models like OWL-ViT and Grounding DINO extend this functionality directly to object localization, letting systems detect any arbitrary object described via text without requiring costly retraining on labeled examples of that specific object. Meanwhile, advanced segmentation tools like Meta’s Segment Anything Model 2 offer promptable, zero-shot segmentation for both static images and complex video streams. By providing a simple point, bounding box, or text prompt, users and upstream systems can generate high-quality segmentation masks instantly.
Moving beyond two-dimensional image understanding, the third stage of the discipline dives into three-dimensional vision, neural rendering, and spatial perception. As computer vision applications expand into robotics and autonomous navigation, the required skill set shifts toward algorithms that reconstruct the three-dimensional world from two-dimensional inputs. Professionals work extensively with point clouds, voxel grids, and signed distance fields, each presenting distinct memory characteristics and computational costs.
Monocular depth estimation has become the primary entry point for modern three-dimensional workflows. Advanced models like Depth Anything v2 produce relative and metric depth maps from a single standard RGB image, completely eliminating the need for specialized auxiliary depth sensors in many applications. Simultaneously, neural rendering techniques have matured dramatically. While Neural Radiance Fields initially revolutionized novel view synthesis, 3D Gaussian Splatting has provided a faster, significantly more memory-efficient alternative that enables real-time, interactive view synthesis on standard consumer-grade hardware.
Spatial perception is particularly vital for robotics and autonomous systems, requiring a firm grasp of Visual Odometry and Simultaneous Localization and Mapping. These complex algorithmic techniques enable machines to estimate their own physical position within an environment while incrementally building a persistent map using only camera stream inputs.
The final frontier of computer vision engineering is where high-level systems engineering meets physical hardware constraints. A model that performs exceptionally well on a powerful desktop GPU workstation does not automatically translate into a viable production asset. Successfully deploying computer vision systems so they run reliably on constrained hardware, at extremely low latencies, and without unacceptable accuracy loss represents a distinct and highly valued professional discipline.
Model compression forms the first line of optimization, utilizing pruning, quantization, and knowledge distillation to shrink massive foundation models into lean execution assets. Once optimized, these models must interface with specific hardware execution frameworks. Tools like NVIDIA TensorRT and ONNX Runtime serve as the standard deployment paths for GPUs and CPUs, while Intel OpenVINO supports specialized hardware accelerators. For embedded environments, engineers routinely work with dedicated edge modules and emerging neural processing units.
Managing high-throughput, multi-camera streaming introduces significant pipeline engineering challenges. Handling RTSP stream ingestion, synchronizing frames across multiple cameras, batching data efficiently, and maintaining strict throughput standards under heavy operational loads requires meticulous systems design. Specialized toolkits like NVIDIA DeepStream remain essential for GPU-accelerated video analytics pipelines operating in real-world production environments.
Ultimately, computer vision engineering is a deeply layered discipline. The underlying mathematics are foundational but no longer sufficient on their own, and while model architectures evolve at a rapid pace, they continue to rest upon stable, enduring mathematical principles. The professionals who stand out most in this rapidly maturing field are those who demonstrate the versatility to move fluidly between various levels of abstraction—bridging the gap between camera geometry, transformer attention patterns, and the instruction sets of physical edge accelerators.