In the rapidly evolving landscape of artificial intelligence development, practitioners often use the terms "prompt engineering" and "prompt optimization" interchangeably. However, industry experts are increasingly drawing a distinct line between the two concepts. While prompt engineering typically involves designing a prompt from scratch for a blank-page framework, prompt optimization focuses on refining an existing, functional prompt through heightened specificity, structural adjustments, and iterative testing—all without altering the underlying large language model itself.
This distinction has become crucial for engineers and developers asking how to extract better, more reliable outputs from existing LLMs. Most real-world production environments already utilize working prompts; what teams typically lack is empirical guidance on which specific modifications genuinely improve performance and which merely offer the illusion of progress.
To address this gap, software engineer and technical writer Shittu Olumide recently outlined five core prompt optimization strategies. Rather than relying on folk wisdom, these strategies are backed by analytical sources and tested against a deliberately complex, real-world scenario: a messy meeting transcript that requires conversion into a clean, accurate list of actionable tasks.
The test transcript features three speakers discussing various corporate projects while navigating genuine conversational ambiguity. Three distinct elements make the extraction process difficult: a mobile layout review that is reassigned mid-conversation from one participant to another, a tablet breakpoint check that is folded into that same review rather than broken out into a separate line item, and a support-queue triage task whose ownership is explicitly left unresolved rather than silently dropped or inaccurately guessed.
In professional software development, a prompt that handles the straightforward aspects of a conversation while missing these nuanced details is considered a failure, even if its initial output appears plausible at a glance. Addressing this gap requires moving beyond trial-and-error prompting toward rigorous, measurable optimization techniques.
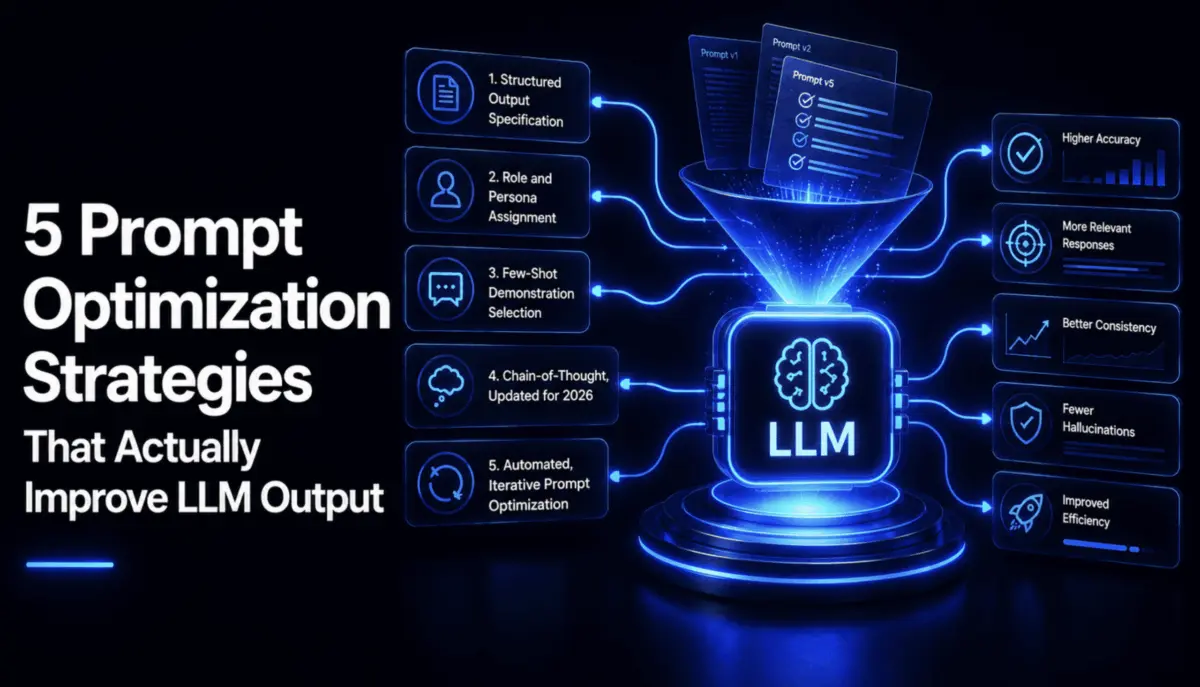
The first major strategy involves specifying structured output. Asking a model in plain prose to list action items typically yields a readable, fluent response that downstream software systems cannot reliably parse. In production environments, unparseable output represents a hard system failure rather than a minor inconvenience. By implementing strict schema validation—using libraries like Pydantic to enforce data structures containing specific fields for owners, tasks, and deadlines—developers can ensure that model outputs map cleanly into validated objects. Testing shows that while vague prose prompts fail to parse automatically, explicit schema requests yield data that code can directly consume without requiring manual human transcription.
The second strategy centers on assigning a precise role and persona to the model. Designating a specific professional background activates relevant portions of the model’s training data, producing more context-aware outputs than generic instructions alone. For instance, instructing a model to act as a meticulous executive assistant who understands mid-sentence changes and unconfirmed assignments primes the system to watch for conversational ambiguity before it begins processing the text. This contextual priming proves especially vital when analyzing transcripts where a careless first pass would easily overlook shifting responsibilities.
The third strategy focuses on the careful selection of few-shot demonstrations. Research indicates that the specific examples chosen for demonstration can have a greater impact on output quality than the wording of the instructions themselves. Furthermore, combining well-chosen examples with clear instructions consistently outperforms either approach in isolation. The key challenge lies in selecting diverse examples rather than multiple variations of the exact same pattern. By utilizing distance metrics and vectorization techniques to identify and remove near-duplicate examples, developers can ensure their few-shot demonstration set covers genuinely distinct scenarios—such as a confirmed owner, an explicitly unresolved owner, and an absorbed task—providing the model with a comprehensive range of patterns to evaluate.
The fourth strategy involves prompting for chain-of-thought reasoning. While frontier models now reason natively to a certain degree, explicitly requesting step-by-step logic remains highly effective for genuinely ambiguous cases like mid-conversation reassignments. Forcing a model to trace ownership across the entire discussion before extracting action items prevents it from latching prematurely onto initial mentions and missing subsequent corrections. For cost-conscious development teams, emerging techniques such as drafting reasoning steps in abbreviated formats allow systems to match full chain-of-thought accuracy while significantly reducing token consumption.
The final and most advanced strategy is automated, iterative prompt optimization. Rather than hand-tuning prompts based on intuition, developers can score candidate prompt fragments against real test cases and use search algorithms to discover the most effective modifications. By evaluating metrics such as recall, owner accuracy, and penalties for fabricated items, automated search processes can identify the minimum set of instructions required to achieve optimal performance. In practical tests, automated hill-climbing search algorithms successfully isolated the exact corrective fragments needed for complex transcripts, reaching perfect accuracy without cluttering the prompt with unnecessary instructions.
Layering these strategies together transforms prompt development from an exercise in guesswork into a disciplined, verifiable engineering process. By combining structured output schemas, contextual role assignments, diverse few-shot demonstrations, targeted reasoning prompts, and automated iterative refinement, development teams can eliminate the hidden errors that often plague automated data extraction, ensuring greater reliability in production environments.