A recurring friction point in enterprise artificial intelligence has long been the massive chasm between vendor-quoted project costs and the actual, underlying economics of model training. When one corporate development team recently received a commercial quote of fifty thousand dollars to construct a custom AI model trained on internal support tickets, a skeptical engineer decided to investigate. Spending a single weekend testing the core methodology behind the vendor’s proposal, the engineer successfully executed the entire training pipeline for less than ten dollars in raw compute costs.
That staggering discrepancy is neither a rounding error nor an isolated incident. For years, the process of fine-tuning large language models has carried a reputation as an exclusive research-lab activity. For full-scale training runs of frontier foundational models from scratch, that reputation remains entirely accurate, with costs routinely scaling into the tens or hundreds of millions of dollars. However, the operational reality of adapting existing open-weight models to specific business tasks has shifted into an entirely different financial category. While technical documentation has historically suffered from a lack of transparency, focusing on isolated methods or omitting runnable code implementations, modern parameter-efficient techniques and optimization tooling have fundamentally altered the landscape. Industry practitioners now possess access to structured approaches that dramatically reduce both compute requirements and infrastructural overhead without sacrificing model performance.
What Fine-Tuning a Large Language Model Actually Means
To understand the economic shift, industry analysts emphasize the precise technical distinction between fine-tuning and alternative methods for shaping model behavior. Fine-tuning takes a foundational model that has already undergone extensive pretraining on a broad corpus and subjects it to additional training on a narrower, task-specific dataset. This process shifts the model’s behavioral tendencies measurably toward a specific formatting requirement, professional domain, or consistent corporate tone without necessitating training from the ground up.
This approach sits alongside other adaptation strategies, such as prompt engineering, few-shot examples, and retrieval-augmented generation. These alternative methods shape model outputs dynamically during inference without altering a single underlying weight. Because they require no training runs, they remain faster to prototype and easier to update. Fine-tuning, by contrast, represents a permanent modification to the model itself. According to industry guidance released in 2026, this heavier operational commitment means organizations must carefully evaluate whether altering model weights is genuinely necessary before undertaking a training project.
Why Teams Actually Fine-Tune
While commercial pitches often suggest that fine-tuning is a universal fix for model shortcomings, advanced frontier models managed with optimal prompt engineering frequently deliver exceptional baseline performance. Consequently, technical leads point to specific operational scenarios that justify the transition to fine-tuning. These typically include embedding specialized proprietary data formats that prompt structures cannot reliably capture, achieving hyper-specific stylistic or tonal consistency across high-volume outputs, or compressing complex domain knowledge directly into a smaller, faster model to reduce latency during production inference.
Conversely, industry best-practice reports indicate that roughly eighty percent of corporate requests framed around the necessity of fine-tuning can be successfully resolved through improved retrieval-augmented generation instead. When an organization faces a retrieval or prompting deficiency, fine-tuning serves as an unnecessarily expensive and durable patch. However, when domain-specific structural constraints apply, fine-tuning provides a permanent capability upgrade.
Which Large Language Models Can Actually Be Fine-Tuned
The democratization of model adaptation relies heavily on the availability of robust open-weight model families supported by mature software ecosystems. Prominent model series such as Llama, Qwen, Mistral, Gemma, and Phi provide strong foundational performance across varying parameter scales, allowing engineering teams to apply cost-saving techniques uniformly. Furthermore, organizations seeking to bypass internal training infrastructure entirely can leverage managed fine-tuning platforms provided by cloud leaders, alongside pay-per-token services offered by specialized infrastructure providers that trade marginally higher operational fees for zero infrastructure management.
A notable technical caveat involves model architecture and scale. Dense models falling within the two to thirteen billion parameter range run comfortably on single-GPU hardware configurations. Once models exceed approximately seventy billion parameters, or utilize sparse mixture-of-experts architectures, memory constraints necessitate multi-node hardware clusters just to accommodate quantized weight states.
The Real Cost of Fine-Tuning a Large Language Model
Evaluating financial expenditures requires examining the complete lifecycle of a model adaptation project rather than focusing solely on raw compute rentals. Parameter-efficient methodologies applied to compact models routinely incur GPU time costs under ten dollars. Conversely, full-scale fine-tuning on premium infrastructure can surpass ten thousand dollars. Verified industry data from mid-2026 indicates that executing low-rank adaptations on seven to eight-billion-parameter models consumes between three and ten dollars in standard cloud GPU time over a multi-hour window, while larger seventy-billion-parameter runs scale up moderately.
Nevertheless, enterprise project planning reveals that direct compute costs frequently constitute the smallest line item in an overall budget. Dataset curation, iterative hyperparameter tuning, and rigorous evaluation represent the primary labor and resource expenditures, recurring whenever a foundational base model receives an upstream update. Consequently, comprehensive real-world projects frequently total between five thousand and fifteen thousand dollars even when raw hardware rentals remain minimal.
Algorithmic and Tooling Optimization Techniques
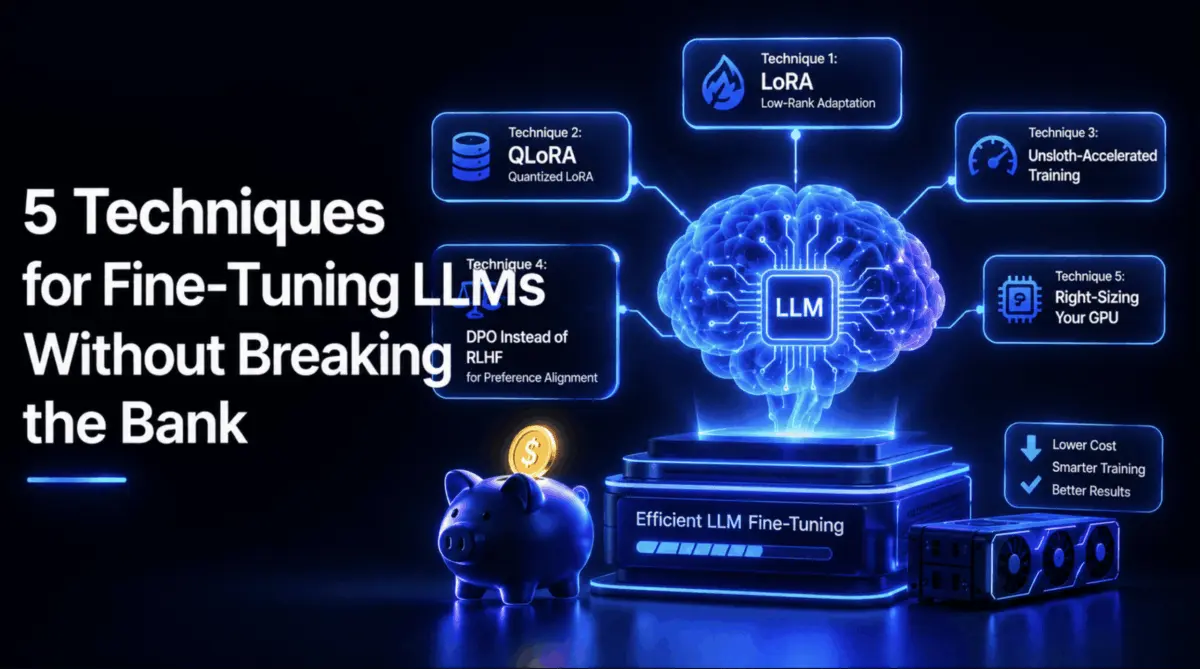
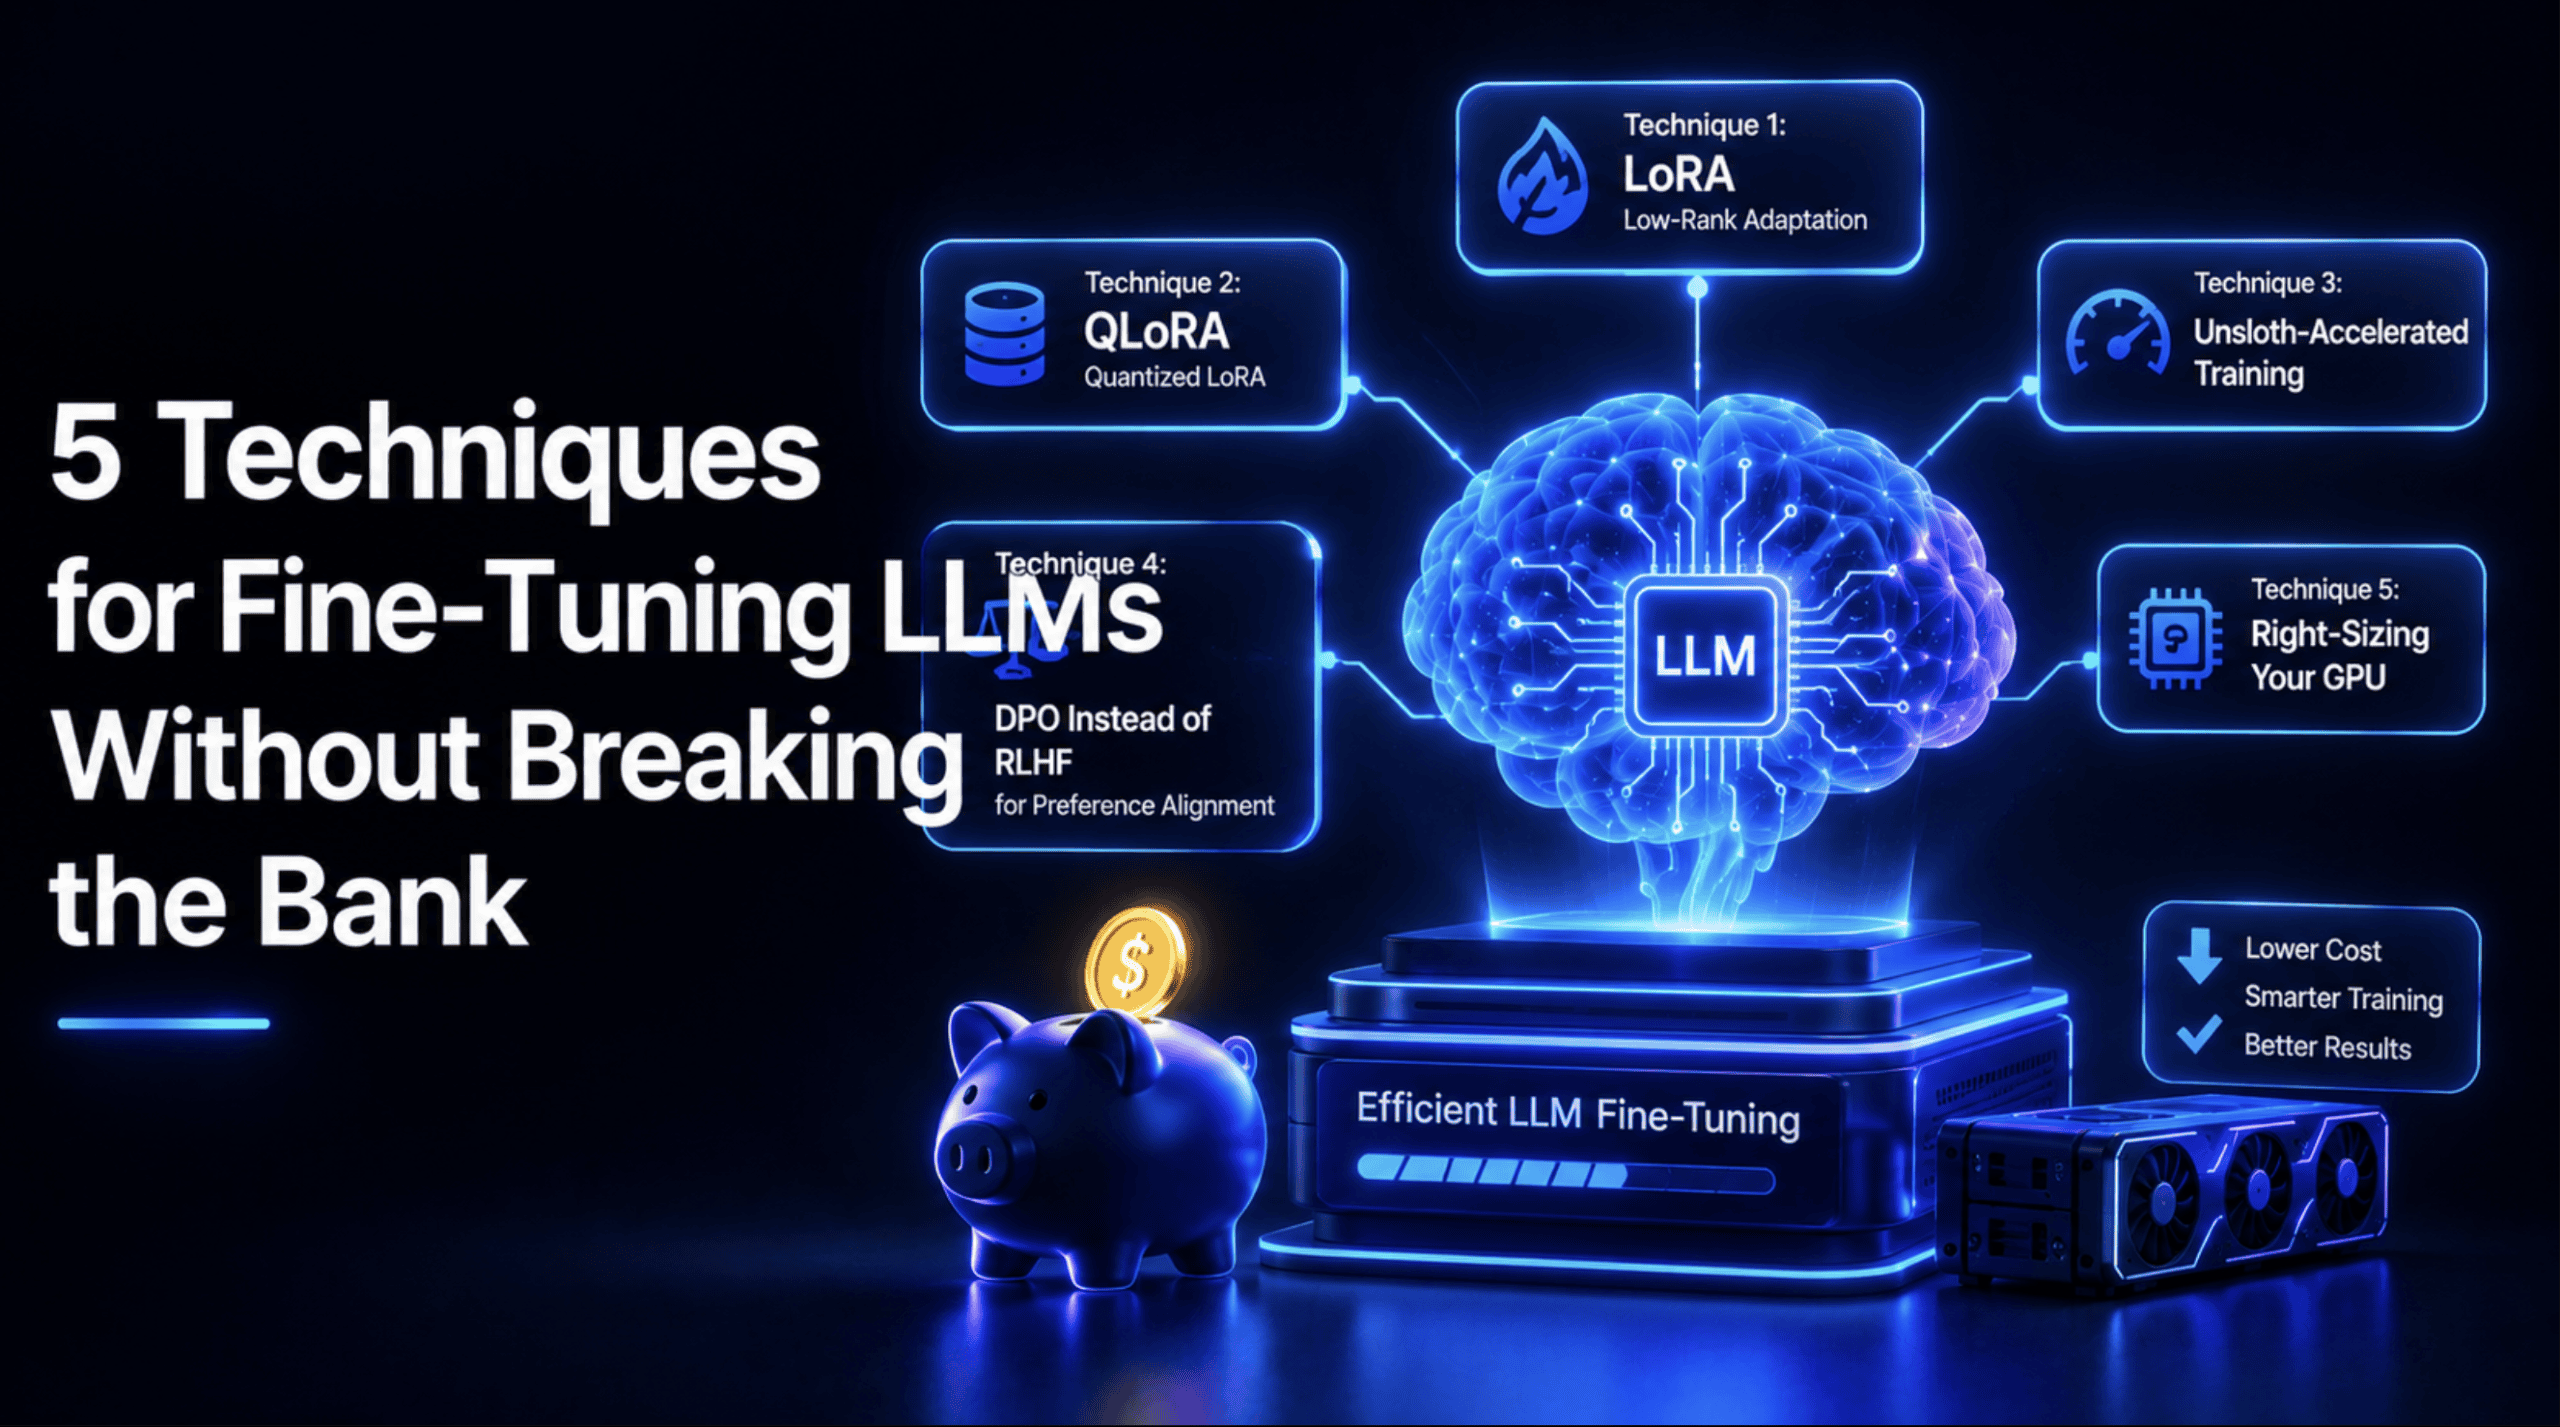
The strategy for reducing fine-tuning expenditures relies on a combination of algorithmic efficiencies, specialized tooling, and infrastructure procurement. Low-rank adaptation, or LoRA, serves as a foundational methodology by freezing the entire base model and introducing small, trainable low-rank matrices. Rooted in the premise that task-specific weight adjustments possess a low intrinsic rank, this technique restricts training to a tiny fraction of total model parameters, often remaining well under one percent.
To eliminate hardware barriers further, quantized low-rank adaptation, or QLoRA, applies four-bit quantization to the frozen base model while maintaining higher precision within the adapter matrices. This process reduces memory consumption by approximately seventy-five percent, enabling models that once required high-end professional hardware to execute efficiently on accessible consumer-grade GPUs.
In tandem with algorithmic adjustments, software-level optimizations provide significant acceleration. Tooling frameworks such as Unsloth replace standard GPU operations with hand-optimized kernels, cutting both training duration and peak memory utilization for existing LoRA and QLoRA setups. Because cloud GPU resources are billed by the hour, reductions in wall-clock training time translate directly into immediate financial savings.
Advanced Alignment and Infrastructure Decisions
Beyond supervised fine-tuning, preference alignment represents a critical phase for ensuring model safety and tonal compliance. Traditional reinforcement learning from human feedback requires complex reinforcement learning pipelines operating against a separately trained reward model, introducing significant computational overhead and training instability. Direct preference optimization bypasses the reward model entirely, training directly on ranked preference pairs using a streamlined classification loss function. This approach simplifies the architectural pipeline while maintaining rigorous alignment control.
Finally, hardware procurement decisions heavily influence overall project economics. Organizations frequently commit the avoidable error of provisioning expensive frontier hardware for lightweight adapter training tasks that standard consumer GPUs handle effectively. By accurately estimating training workloads and token processing throughput in advance, engineering teams can match projects to appropriate hardware tiers, avoiding unnecessary cloud expenditures and ensuring efficient resource utilization across enterprise artificial intelligence initiatives.