Every year, industry events like Big Data London serve as a vital temperature check for the enterprise technology sector. They offer a clear window into not only what software vendors are actively pitching to the market, but more importantly, what practitioners are wrestling with in their day-to-day operations. This year’s gathering proved to be no exception. Following two intense days of presenting research, engaging with industry peers, and listening to the pressing concerns of enterprise customers, several distinct themes emerged with unmistakable clarity regarding the current state of data management and artificial intelligence.
The AI Conversation is Shifting From "What Can It Do?" to "Can We Trust It?"
The single most consistent theme echoing across the exhibition floor and conference rooms was trust—and this concern was voiced not in an abstract or theoretical sense, but with practical urgency. Enterprise leaders and technical practitioners alike want to know how they can verify that their artificial intelligence models are making the correct operational calls. This fundamental question arose in nearly every single conversation, cutting effortlessly across diverse industries and varied organizational roles.
What struck many industry veterans attending the event is that most enterprises have already successfully connected the answer back to their foundational data assets. Just a year ago, discussions were dominated by hand-wringing over the sophistication, parameter sizes, and capabilities of the underlying machine learning models themselves. This time around, however, a more grounded realization was rapidly settling in across the board: an artificial intelligence system is only ever going to be as good as the information fed into it. Organizations now widely recognize a fundamental truth of modern computing—you simply cannot trust the output if you cannot trust the input.
This widespread acknowledgment indicates that the enterprise conversation surrounding artificial intelligence is finally maturing and moving in the right direction. Rather than chasing flashy capabilities built on shaky foundations, organizations are refocusing their attention on the raw material that powers these intelligent systems.
Why is Governance Suddenly Everyone’s Favorite Word?
Data governance was a ubiquitous presence at Big Data London this year, though refreshingly, it was rarely discussed in the typical, dry compliance-driven sense of the past. Instead, professionals are talking about governance as the core operational mechanism that makes artificial intelligence trustworthy at scale. Discussions centered heavily on the need for consistent definitions, clear data lineage, and strict rules that travel seamlessly with data as it moves across disparate enterprise systems.
The energy and enthusiasm surrounding data governance felt genuinely new. For a long time within corporate IT departments, governance was treated as an afterthought—the administrative chore that organizations casually claimed they would get around to "eventually."
However, the rapid deployment of autonomous artificial intelligence systems changes the equation entirely. Because modern AI systems are increasingly acting autonomously on organizational data, the potential stakes of skipping robust governance are visible in a way they never were before. When a legacy model runs on inconsistent, ungoverned data, it might produce a wrong report. But when an autonomous agent runs on that same flawed data, it can take a wrong action with immediate business consequences. That represents an entirely different category of operational risk.
What is the Context Gap, and Why Does It Matter for AI?
Another prominent theme that surfaced repeatedly during discussions relates to a growing friction point between enterprises and their data suppliers. Companies increasingly feel that their external data suppliers are not doing enough to help them manage the critical context layer required for advanced analytics.
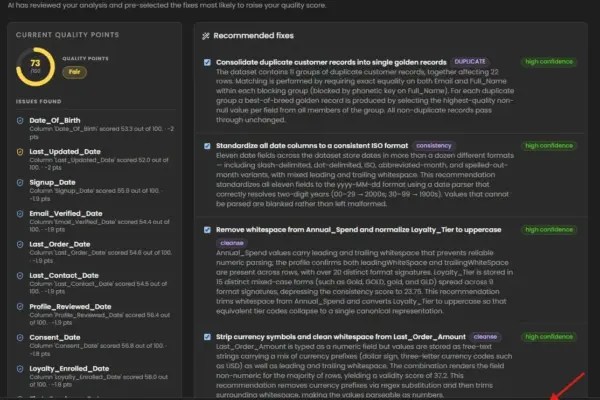
When an artificial intelligence system attempts to reason about complex enterprise data, raw numbers and isolated strings of text are rarely enough. The system desperately requires deep, underlying meaning to interpret those records accurately. This semantic and contextual richness forms the core of what truly makes enterprise data ready for artificial intelligence applications.
This exact challenge is precisely where data enrichment becomes a vital necessity for modern organizations. Data that arrives at an enterprise with pre-linked context, verified attributes, and robust real-world grounding provides artificial intelligence systems with the complete picture they require to function effectively. Without that contextual layer, organizations are essentially asking sophisticated models to reason using incomplete information. While the models will still generate an answer, enterprises will rarely be able to trust the validity of that output.
What Role Does Location Intelligence Play in AI?
Among the numerous topics addressed during conference speaking sessions, the role of location data sparked some of the longest and most engaged follow-up conversations. Attendees showed immense interest in exploring how modern location intelligence can provide a distinct competitive edge. Specifically, professionals discussed how spatial data can be leveraged to effectively connect disparate records, enrich customer profiles, ground artificial intelligence decisions in physical reality, and identify emerging operational risks.
This strong appetite for location-based solutions made intuitive sense given the broader industry trends. Location intelligence stands out as one of the most effective methods available for providing artificial intelligence systems with a comprehensive, holistic picture of the real-world entities they are designed to analyze. Without geographic and spatial dimensions, organizations are frequently forced to work exclusively from internal enterprise data that lacks the essential physical-world context needed to make high-stakes decisions with absolute confidence. By incorporating location data into the mix, businesses gain enhanced accuracy, better explainability, and a strategic advantage that the vast majority of organizations are still underutilizing.
This deep capability is fundamentally embedded in how forward-thinking data organizations approach the market. If artificial intelligence systems are going to successfully reason about the physical world, they must rely on data that is firmly anchored to that world. Increasingly, this anchoring is the defining factor that separates accurate artificial intelligence outputs from confident yet entirely wrong ones.
What Are Organisations Going to Do with All These AI Agents?
The rapid proliferation of AI agents was another topic that dominated discussions throughout the event. While the technology generates significant excitement, what proved most valuable were the honest, probing questions raised underneath the hype: What specific business problem does a given agent actually solve? And crucially, what happens when that agent inevitably makes a mistake?
It was during these discussions surrounding error management that the issue of algorithmic bias emerged more prominently than many expected. Industry professionals are acutely aware that artificial intelligence systems have the potential to amplify bad assumptions and historical prejudices already embedded within training data. External data, when utilized correctly, serves as one of the most powerful and effective tools available for mitigating that specific risk. Diverse, high-quality enrichment data supplies crucial context that internal datasets alone simply cannot provide.
At the same time, experts cautioned that this external data must be managed with extreme care, backed by clear lineage and rigorous governance. Failing to do so risks merely shifting the underlying bias problem further upstream into the data supply chain.
What Can You Do to Get Your Data AI-Ready Today?
The rich array of conversations and insights gathered at Big Data London powerfully reinforced a fundamental truth about the current technological landscape: the organizations that ultimately capture the most tangible value from artificial intelligence are those treating data readiness as an immediate, strategic priority.
While the machine learning models themselves are largely ready and the underlying enterprise infrastructure continues to mature at a rapid pace, the single biggest obstacle still facing most corporations is the state of their foundational data.
Fortunately, the industry is rallying to provide solutions to help businesses meet this pivotal moment and overcome their most complex data challenges. Organizations looking to take the next steps are encouraged to explore virtual industry events and resource centers, such as Precisely Now, which focus on delivering the latest insights and technical tools required to achieve true data readiness for the age of artificial intelligence.