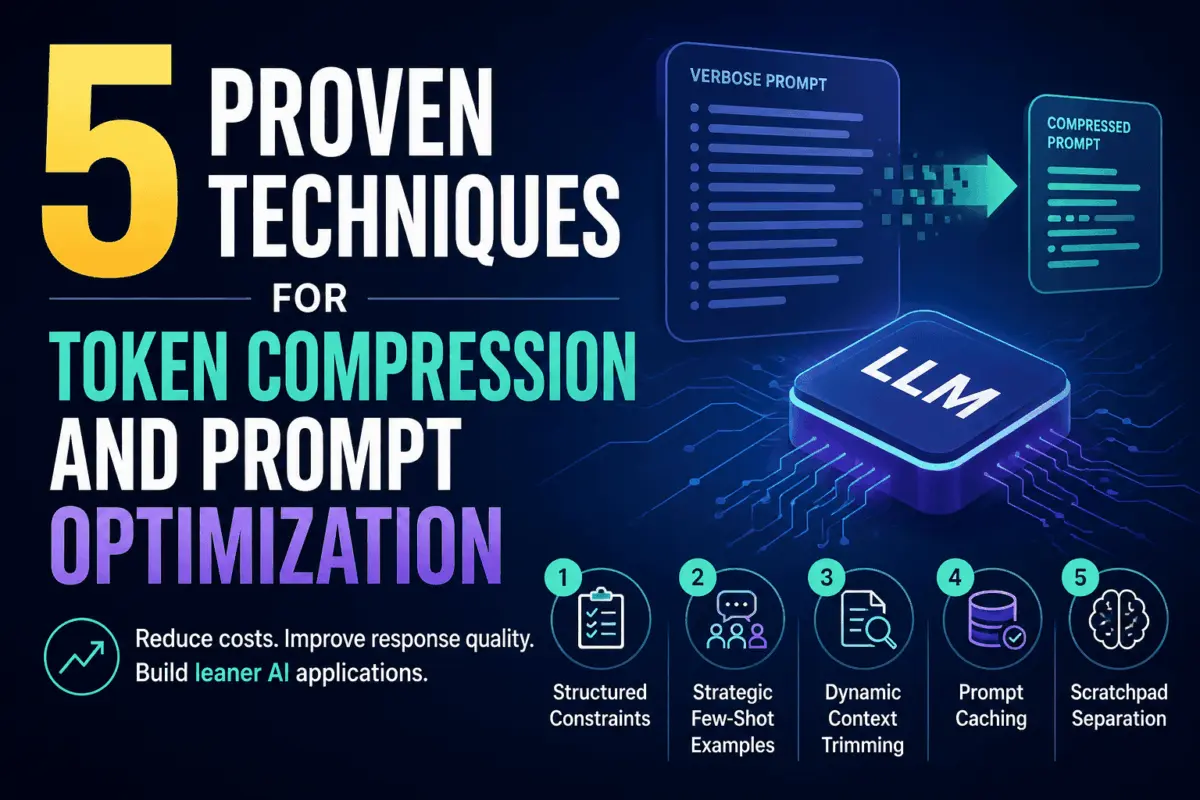
In the rapidly evolving landscape of artificial intelligence development, efficiency has become a critical focal point for engineers and enterprise leaders alike. Whether organizations are scaling production applications powered by large language models or executing experimental workflows in specialized computing notebooks, bloated prompts quietly drain financial resources while simultaneously degrading response quality. Recent insights shared by AI and data science educator Vinod Chugani highlight a pressing industry challenge: the need to transmit maximum semantic intent with minimal token consumption. Token compression and strategic prompt optimization are no longer optional best practices; they are foundational disciplines required to ensure that generative AI models respond with high accuracy and operational efficiency.
The core philosophy behind these optimization practices is rooted in precision. Every single token processed by a large language model incurs a cost, both in terms of financial overhead and computational latency. When system prompts and user inputs are cluttered with conversational filler, redundant instructions, or unrefined context, the model spends valuable processing capacity parsing unnecessary text. Addressing this challenge requires a systematic shift in how developers construct prompts, moving away from verbose, narrative styles toward highly structured, declarative frameworks.
Replacing Verbose Instructions with Structured Constraints
The transition from conversational system prompts to tightly structured constraints represents one of the most immediate opportunities for efficiency gains. Traditional prompt engineering often mirrored human-to-human communication, relying on polite, lengthy instructions to guide model behavior. However, this conversational approach introduces significant token bloat. Engineers frequently write extensive paragraphs detailing formatting rules, behavioral guidelines, and negative constraints.
To mitigate this waste, practitioners are adopting schema-like formatting that modern model architectures parse with high efficiency. By replacing narrative explanations with declarative constraints, developers can drastically reduce input lengths without losing structural clarity. For example, replacing a paragraph of behavioral directives with pipe-delimited key-value pairs or concise schema snippets can slash token counts significantly. Across thousands or millions of daily API calls, these modest reductions compound into substantial operational savings, proving that brevity directly correlates with fiscal and computational prudence in enterprise AI deployments.
Using Few-Shot Examples Strategically, Not Exhaustively
Few-shot prompting remains a vital technique for establishing output format consistency, particularly in classification and structured generation tasks. By providing a handful of input-output examples before the primary request, developers guide the model toward the desired behavioral pattern. Yet, a widespread misconception among practitioners is that more examples inherently yield better performance.
Empirical research from leading AI institutions and academic benchmarks consistently demonstrates diminishing returns beyond a narrow threshold of three to five examples. Exceeding this range rarely improves task accuracy and frequently introduces unintended contradictions that confuse the model’s underlying attention mechanisms. Streamlining few-shot blocks to a lean, highly representative set of examples establishes the necessary pattern while keeping input token counts strictly controlled. Auditing existing production prompts and benchmarking performance across varying example counts allows development teams to strike an optimal balance between precision and cost.
Applying Dynamic Context Trimming for Long Documents
Handling extensive text documents—such as legal transcripts, knowledge base articles, or lengthy conversational logs—presents a persistent challenge in prompt engineering. Passing raw, unrefined documents directly into a context window forces organizations to pay for massive token volumes that the model may not even utilize to answer the specific query.
Dynamic context trimming offers an effective solution by retrieving only the precise passages relevant to the user’s intent rather than transmitting the entire document. Utilizing similarity metrics, such as cosine distance calculated via sentence embeddings, applications can programmatically filter out extraneous information before a prompt is ever dispatched to an inference endpoint. When applied to massive repositories where only a fraction of the text holds actionable relevance, this targeted retrieval method can drastically reduce context-related expenditures without compromising the factual integrity of the generated output.
Caching Repeated Prompt Prefixes with Prompt Caching
Many modern enterprise applications rely on recurring structural elements across every user interaction, including identical system personas, comprehensive tool descriptions, and rigid policy constraints. Repeatedly transmitting these static tokens fresh with every single API call creates an unnecessary drain on system resources.
To address this inefficiency, major AI inference providers have introduced prompt caching mechanisms. Services offered by industry leaders now support server-side storage and reuse of static prompt prefixes, billing these cached segments at a distinctively reduced rate compared to standard input pricing. Structuring applications so that stable system instructions appear at the very beginning of the prompt architecture, followed by semi-static context and dynamic user messages at the end, enables systems to fully leverage these caching protocols. As providers continue to refine their infrastructure, understanding and implementing prefix caching has become essential for scaling conversational agents and automated workflows cost-effectively.
Compressing Chain-of-Thought Reasoning with Scratchpad Separation
Chain-of-thought prompting has transformed the ability of large language models to reason through complex multi-step problems, mathematics, and logic puzzles. However, the internal reasoning trace generated during this process can often span hundreds of tokens. When these intermediate steps appear verbatim in the final API response alongside the actual answer, output token costs escalate rapidly.
Separating the internal reasoning scratchpad from the final deliverable resolves this issue. By instructing the model to execute its step-by-step logic within designated markers or tags and restricting the final output to a concise answer block, applications can programmatically parse and discard the verbose reasoning trace before returning results to the end user. While organizations still incur costs for the generated thinking tokens, filtering them out of storage and user-facing interfaces optimizes downstream data handling. Furthermore, as platforms introduce native reasoning modes with specialized billing structures, adopting structured output separation ensures that engineering teams maintain strict oversight over both input and output resource consumption.
The broader adoption of these optimization practices reflects a maturing artificial intelligence ecosystem. As organizations transition from exploratory prototypes to large-scale production deployments, managing token consumption is inextricably linked to project viability. By focusing on precision, structural efficiency, and intelligent context management, developers can build responsive, cost-effective AI applications that perform at the highest levels of accuracy.