For many newcomers stepping into the fast-paced fields of data science and artificial intelligence, the fundamentals of Python are treated less as a permanent home and more as a crowded waiting room. The prevailing strategy is often to rush through the basics—syntax rules, file handling, and basic loops—as quickly as possible just to arrive at the glamorous libraries where the real work is presumed to happen. It is an entirely understandable plan for anyone eager to build machine learning models, train neural networks, or deploy automated pipelines. However, this educational shortcut produces a very specific kind of practitioner: one who can follow an online tutorial precisely step-by-step, yet becomes entirely stranded the moment a real-world dataset fails to match the pristine conditions of the example.
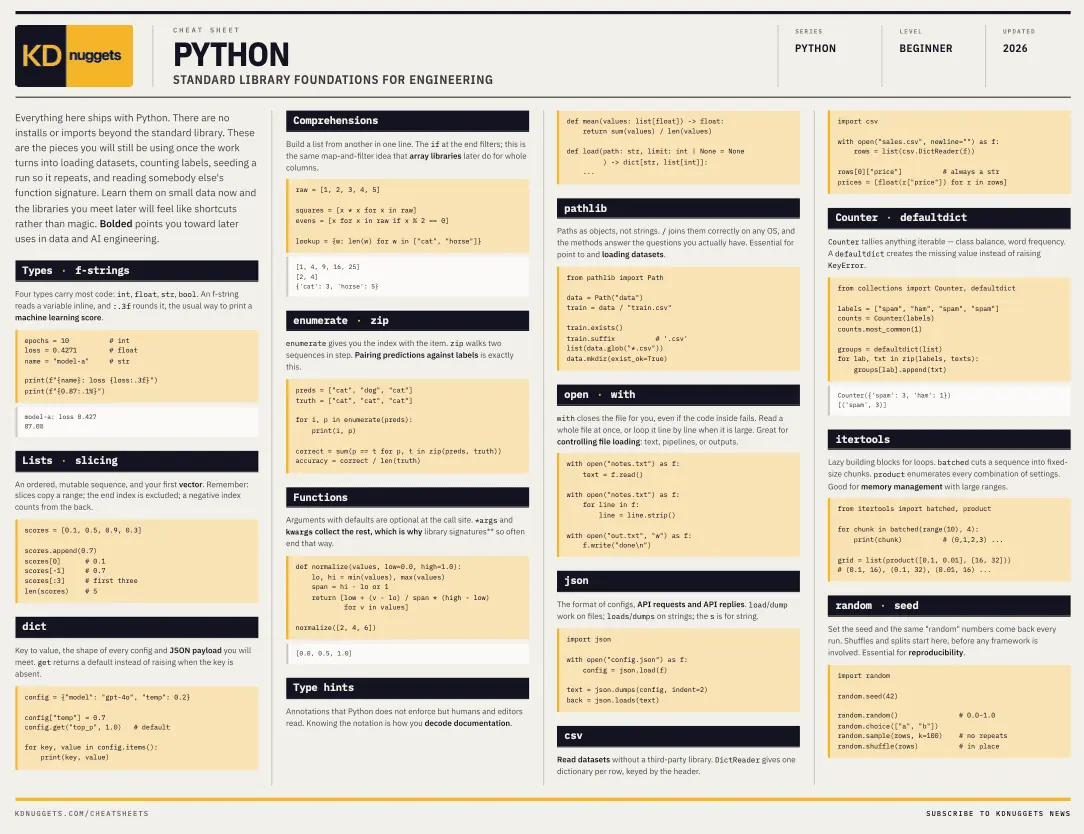
To address this persistent industry challenge, KDnuggets has released its latest resource, the Python Engineering Foundations cheat sheet. Designed to bridge the gap between superficial syntax memorization and deep comprehension, the new reference guide gathers the critical material that does not get left behind when a developer transitions from a novice to a seasoned professional. Almost none of the core concepts featured in the cheat sheet are ever replaced by a higher-level framework later in a developer’s career. Instead, these foundational principles scale up, are executed on faster underlying machinery, and are wrapped in nicer user interfaces, but the underlying mechanics remain identical. A data transformation written across a handful of native items is fundamentally the same logical operation that an advanced array library applies to a column of ten million rows.
Consequently, even if a programmer first encounters a concept on a small, toy dataset, the vectorized or scaled version encountered later is entirely intuitive and understandable without needing to guess or alter code blindly. It is not simply a piece of syntax copied from a forum and pasted with crossed fingers. This distinction matters most when something inevitably breaks in a production environment, because attempting to debug a complex pipeline without understanding the fundamental mechanics is a fool’s game. When an error traceback spans multiple files and frameworks, knowing how native Python handles data types, exceptions, and memory references often separates a quick fix from hours of frustrating guesswork.
Beyond raw execution and debugging, there is profound value in mastering the foundational aspects of reading code natively. Function signatures, optional arguments, collected argument lists, and type annotations that the Python interpreter never strictly enforces at runtime—yet appear throughout the documentation of every major tool—form the universal prose of the software ecosystem. This notation is the language every library you will ever come across uses to describe itself. Not being fully conversant in this specific style of technical prose means that reference documentation effectively remains closed and intimidating. Every roadblock then becomes a desperate quest for somebody who has encountered the issue before, or worse, a reason to consult artificial intelligence tools like ChatGPT for an answer that quietly presupposes an actual understanding of the underlying problem.
When the dust settles on advanced frameworks and specialized packages, what remains are the foundational concepts that underpin the vast majority of any real-world working project. These essential tasks include finding files on a local or cloud filesystem and opening them safely, seamlessly moving between the diverse data formats that configuration files and application programming interface traffic actually arrive in, accurately counting what is inside a dataset before blindly trusting any sweeping claim about its distribution, and properly fixing a random seed so that an experimental result can be reliably reproduced by colleagues or automated auditors. Far from being mere preliminaries or boring administrative tasks to rush through before the real engineering begins, these operations turn out to constitute a remarkably large share of what professional data engineering work actually entails day in and day out.
Addressing this reality requires tools and knowledge that remain stable, dependable, and immune to the shifting trends of the broader technology landscape. Everything featured on the newly released KDnuggets cheat sheet ships natively with standard Python. There is nothing extra to install, no complex dependency trees to manage, no external packages to pin down, and no frustrating version drift to troubleshoot across different development environments. By focusing heavily on these enduring, built-in engineering foundations, the new resource aims to equip the next generation of data practitioners with the enduring competence required to build robust, resilient, and truly understandable systems from the ground up.