Large language models have fundamentally transformed how organizations approach text generation, yet they remain plagued by a persistent and well-documented vulnerability: hallucinations. When operating without direct access to verified, up-to-date information, these models routinely manufacture plausible-sounding answers that are factually incorrect. To combat this limitation, Retrieval-Augmented Generation (RAG) emerged as the industry standard, grounding model outputs in external knowledge sources and successfully reducing hallucinations across a wide array of enterprise applications.
However, as organizations push these artificial intelligence systems into increasingly complex workflows, a new architectural bottleneck has surfaced. Standard RAG pipelines are inherently linear, executing a single retrieval operation, passing those results to the model, and generating a final answer. While this straightforward approach is effective for simple queries and well-structured knowledge bases, it begins to fail when a prompt requires multi-step reasoning, the cross-referencing of disparate sources, or the synthesis of information spanning multiple documents.
Enter Agentic RAG, a paradigm shift that addresses these limitations by redefining how systems interact with external data. Instead of treating retrieval as a single, fixed procedural step, Agentic RAG endows the system with the capacity to reason about its search strategy, critically evaluate what it discovers, and iterate dynamically until it arrives at a comprehensive and accurate answer.
The Baseline: Understanding Naive RAG
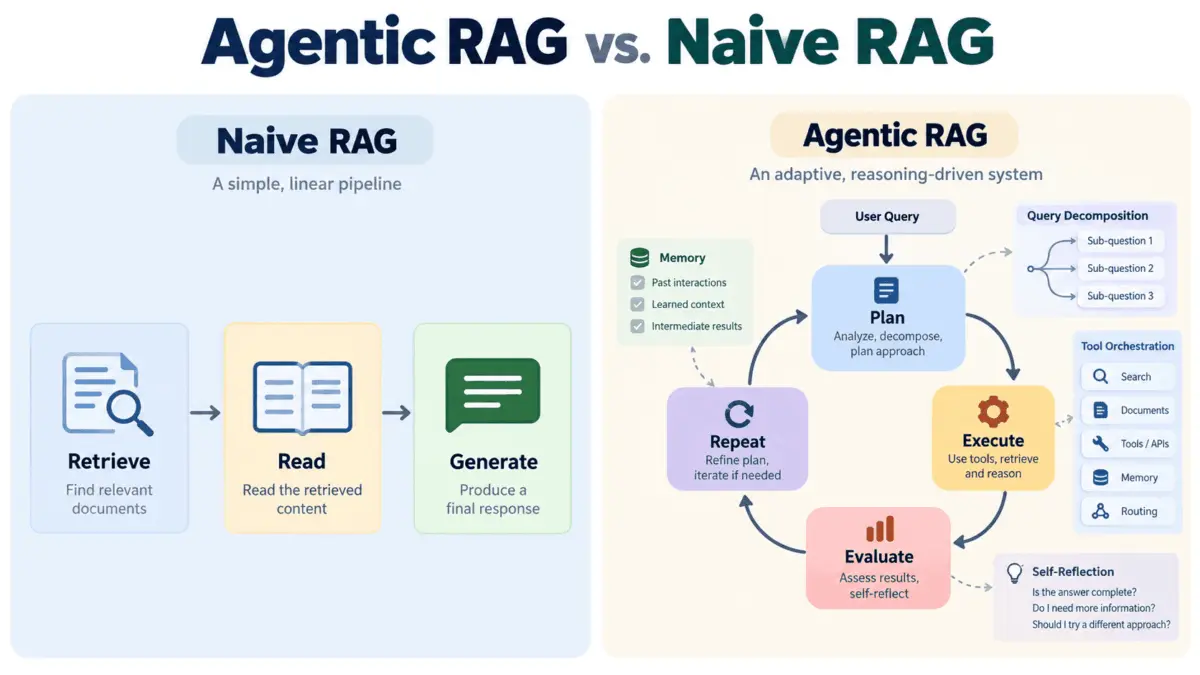
To understand where retrieval architectures are heading, it is necessary to examine their foundational design. Naive RAG—frequently referred to as standard RAG—operates on a rigid, three-stage pipeline consisting of retrieval, reading, and generation. When a user submits a query, the system transforms the text into a vector embedding, performs a similarity search against a vector database, extracts the top-k most relevant document chunks, and injects those chunks into the large language model as context. The model then formulates a response derived exclusively from the provided text.
This mechanism can be likened to a student preparing for an examination inside a vast library by typing a single keyword into a catalog, grabbing the first three books on the nearest shelf, and composing an essay based solely on those volumes without verifying whether they actually address the prompt.
Under the hood, documents are initially ingested, segmented into smaller chunks, and converted into dense vector representations via an embedding model. These vectors find storage in databases optimized for approximate nearest-neighbor searches. During inference, the user query undergoes the same embedding process, and the database yields the chunks positioned closest in high-dimensional space. These segments are subsequently passed into the model’s context window.
This architecture represented a genuine breakthrough for enterprise technology. Naive RAG enabled the deployment of reliable question-and-answering systems, internal knowledge assistants, and document summarizers anchored in verified data. For many straightforward applications, this baseline approach remains an efficient and cost-effective choice.
The Bottleneck: Where Naive RAG Breaks Down
Despite its widespread adoption, the core weakness of standard RAG lies in its linearity. A single retrieval pass either succeeds or fails. If an initial query is poorly formulated, if the necessary information is scattered across multiple locations, or if the question demands multi-layered reasoning, the pipeline lacks the mechanisms required to recover.
Naive RAG is fundamentally limited by its single-pass nature. If the vector embedding of a query fails to surface the correct document chunks, the model is forced to generate a response from incomplete or irrelevant context. The system cannot recognize its own retrieval failure, nor can it adjust its strategy.
This rigidity becomes particularly acute during multi-hop reasoning tasks. For example, consider a complex prompt inquiring about the regulatory policies followed in the European Union by the company that acquired WhatsApp. Answering this question correctly requires at least two distinct steps: identifying the acquiring entity, and subsequently retrieving the specific regulatory framework governing that entity within the EU. A standard vector search targeting WhatsApp’s EU regulatory policies directly will frequently fail to bridge this connection, especially if the relevant facts reside in separate documents. Standard RAG pipelines possess no inherent ability to decompose such prompts into sequential sub-questions, retrieve intermediate answers, and feed those findings into a secondary search.
Furthermore, standard retrieval pipelines remain highly susceptible to poor search results. When the retrieved document chunks are irrelevant to the user’s intent, the language model is placed in an untenable position. It must either ignore its grounding context—thereby triggering hallucinations—or issue an unhelpful statement indicating a lack of sufficient information. Within high-stakes enterprise environments, neither outcome is acceptable.
Agentic RAG: Giving the System a Brain
Agentic RAG reframes the entire retrieval problem by transforming the language model from a passive text generator into an autonomous reasoning engine that actively orchestrates the retrieval lifecycle. Where standard RAG functions as a static pipeline, Agentic RAG operates as a continuous loop of planning, execution, evaluation, and iteration.
Returning to the library analogy, a dedicated research assistant does not simply grab the first few books and begin writing. They read the initial sources, identify missing pieces of evidence, consult alternative databases, cross-reference conflicting claims, and only compile their final text once they are confident in the completeness of their research. Agentic RAG builds this investigative behavior directly into the artificial intelligence architecture.
In this framework, the model is no longer a downstream consumer of retrieved context. Instead, it acts as an orchestrator, determining what information is required, where it should be retrieved from, whether the retrieved results meet quality standards, and how to proceed if they fall short. This approach converts retrieval from a preliminary pre-processing step into a dynamic, self-correcting workflow.
Four Mechanisms That Make RAG Agentic
The functional gap between standard and agentic pipelines is bridged by four distinct architectural mechanisms, each designed to resolve specific failure modes inherent to linear retrieval.
Query routing allows the system to determine the most appropriate data source before executing a search. Because different inquiries demand different repositories—such as a structured SQL database for financial analysis, unstructured documents for corporate policies, or live web searches for current events—query routing empowers the model to evaluate the incoming prompt and select the correct tool from a predefined registry. This prevents the inefficiency of forcing every request through a single semantic search mechanism.
Query decomposition tackles complex, multi-faceted questions by breaking the original prompt into smaller, independently answerable sub-components before initiating retrieval. Using the WhatsApp acquisition scenario as an example, the system avoids searching for the complete phrase at once. Instead, it first identifies the parent company, retrieves the answer, and uses that intermediate finding to construct a more precise secondary query regarding regulatory compliance. This sequential reasoning chain enables the system to build toward a comprehensive answer through targeted searches.
Self-reflection and critique represent perhaps the most consequential capabilities of agentic systems. Following a retrieval pass, the system pauses to evaluate whether the retrieved chunks actually answer the user’s question, checking for relevance and noise. If the model determines the context is insufficient or contradictory, it rewrites the query and initiates a new retrieval cycle. This evaluation-and-retry loop continues until a confidence threshold is met or an iteration limit is reached, preventing runaway loops while ensuring that bad context is never silently passed to the generator.
Finally, tool use and function calling expand the operational scope of the retrieval system. Rather than remaining confined to text databases, the language model can invoke external utilities mid-reasoning, including calculators, live search application programming interfaces, structured database executors, or proprietary internal APIs. By combining retrieved text with live computation and structured data queries within a single reasoning loop, the system transitions from a document retriever into a general-purpose problem-solving engine.
Making the Choice: When to Use Which
Deciding between standard RAG and Agentic RAG requires balancing computational cost against functional capability. Standard RAG involves a single embedding operation and one model call, yielding low latency, predictable expenses, and straightforward debugging. Conversely, Agentic RAG incorporates multiple reasoning steps, increasing both latency and token consumption due to iterative retrieval passes and tool invocations.
Organizations typically select standard RAG for high-volume, low-complexity applications where domain knowledge is homogenous and queries are direct. Agentic RAG is deployed when workflows demand multi-step reasoning, cross-referencing across heterogeneous databases, or strict adherence to accuracy standards where retrieval failures carry high operational costs. Many production environments employ a hybrid model, directing routine queries through a fast standard pipeline while reserving agentic loops for complex or high-stakes prompts.
Ultimately, the distinction between these architectures reflects a broader design principle: the difference between a rigid pipeline and an adaptive loop. While simpler systems remain ideal for direct, well-formed searches, the added complexity of an agentic approach provides essential capabilities for applications requiring advanced reasoning, diverse data integration, and rigorous verification.